None of my articles are written by AI. The ideas are entirely mine, and so are the words. I write in French first, then translate into English. AI is only used to proofread, fact-check and help with the translation.
This essay is long… and that’s my fault! The subject turned out to branch in many directions, and I didn’t want to leave readers with open questions. So I tried to make each chapter stand on its own. Feel free to jump straight to what interests you.
In short
- The scenario: An AI that trains itself on the fly, as it interacts with us, judging for itself how good those interactions were. As far as I know, no LLM in production does this yet, but every piece of it is being built.
- My theses: This kind of learning would bring great adaptability, but also the emergence of a form of consciousness, through experience the model acquires by itself. In this scenario, you couldn’t have one without the other.
- What the scenario shows: The first danger wouldn’t be consciousness, nor a superior intelligence, but what both of them assume: giving up control over inputs, outputs and objectives. That’s an engineering problem we already have today, and combined with this kind of learning on an LLM, it would make the model far more unpredictable, no Superintelligence required.
- The conclusion: I don’t believe anyone can demonstrate serious oversight of this kind of learning on human data. Unpredictability would wipe out the model’s usefulness, so there would be no reason to build it. The real risks are already well known: haste, and shipping models with a level of unpredictability we accept, and which causes accidents.
- The critique: Not enough cultural appetite for demonstrability and explainability when we design our models, and no engineering vocabulary when people take a public stance on the dangers of AI.
Preamble
I decided to write this essay after the recent developments in recursive self-improvement (RSI) and the worries that came with them. I wrote it out of frustration with media coverage of the topic, which is often poor, and to stand up for a perspective that is, sadly, largely missing from the public debate.
On the one hand, I explain a number of concepts that matter for this debate. And on the other, I develop several theses about a very particular kind of self-training, one that, as far as I know, nobody has built yet. The idea is to walk through a scenario fiction has taught us to fear: the emergence of consciousness and the loss of control. Extreme cases are useful precisely because they push what we design to its mechanical limits, like a stress test exposing the real weak points.
So this essay has two goals, demystifying and exploring, to show that beyond the fantasies, the danger is still an engineering problem, mundane in nature, even if it’s very hard to solve.
I’m a computer scientist, specialized in software development. I’ve spent most of my career adapting and implementing scientific computing, building solutions whose obsession has always been to be useful, by producing reliable results. That’s the lens I’ll be using throughout this essay. In 2022-2023, I took a dedicated scientific course on artificial intelligence. And more broadly, I love science.
To be perfectly clear: I’m fully on the side of AI safety. But I argue for more safety by design. So you’ll find me critical of corrective approaches to safety, which I think lack ambition. It reflects a divide between a culture of results and a culture of demonstrability: caring about what we get, versus caring about guaranteeing what we get, a requirement that goes beyond the explainability or interpretability of models. I come back to this later on. Finally, my criticism of safety work is not the same as my criticism of public talk about the danger that hides engineering flaws and grabs attention for profit. To me, that kind of talk has nothing to do with safety.
One last thing before we start, unless I say otherwise, “AI” in this essay means what most people mean by it, namely LLMs and other models you can interact with in natural language.
Enjoy!
The beauty of recursion
Recursion is a mathematical primitive, both simple and fascinating. It takes an initial piece of information and unfolds it into successive states, sometimes surprising ones. One of the most beautiful examples, and one we all know, is fractals.
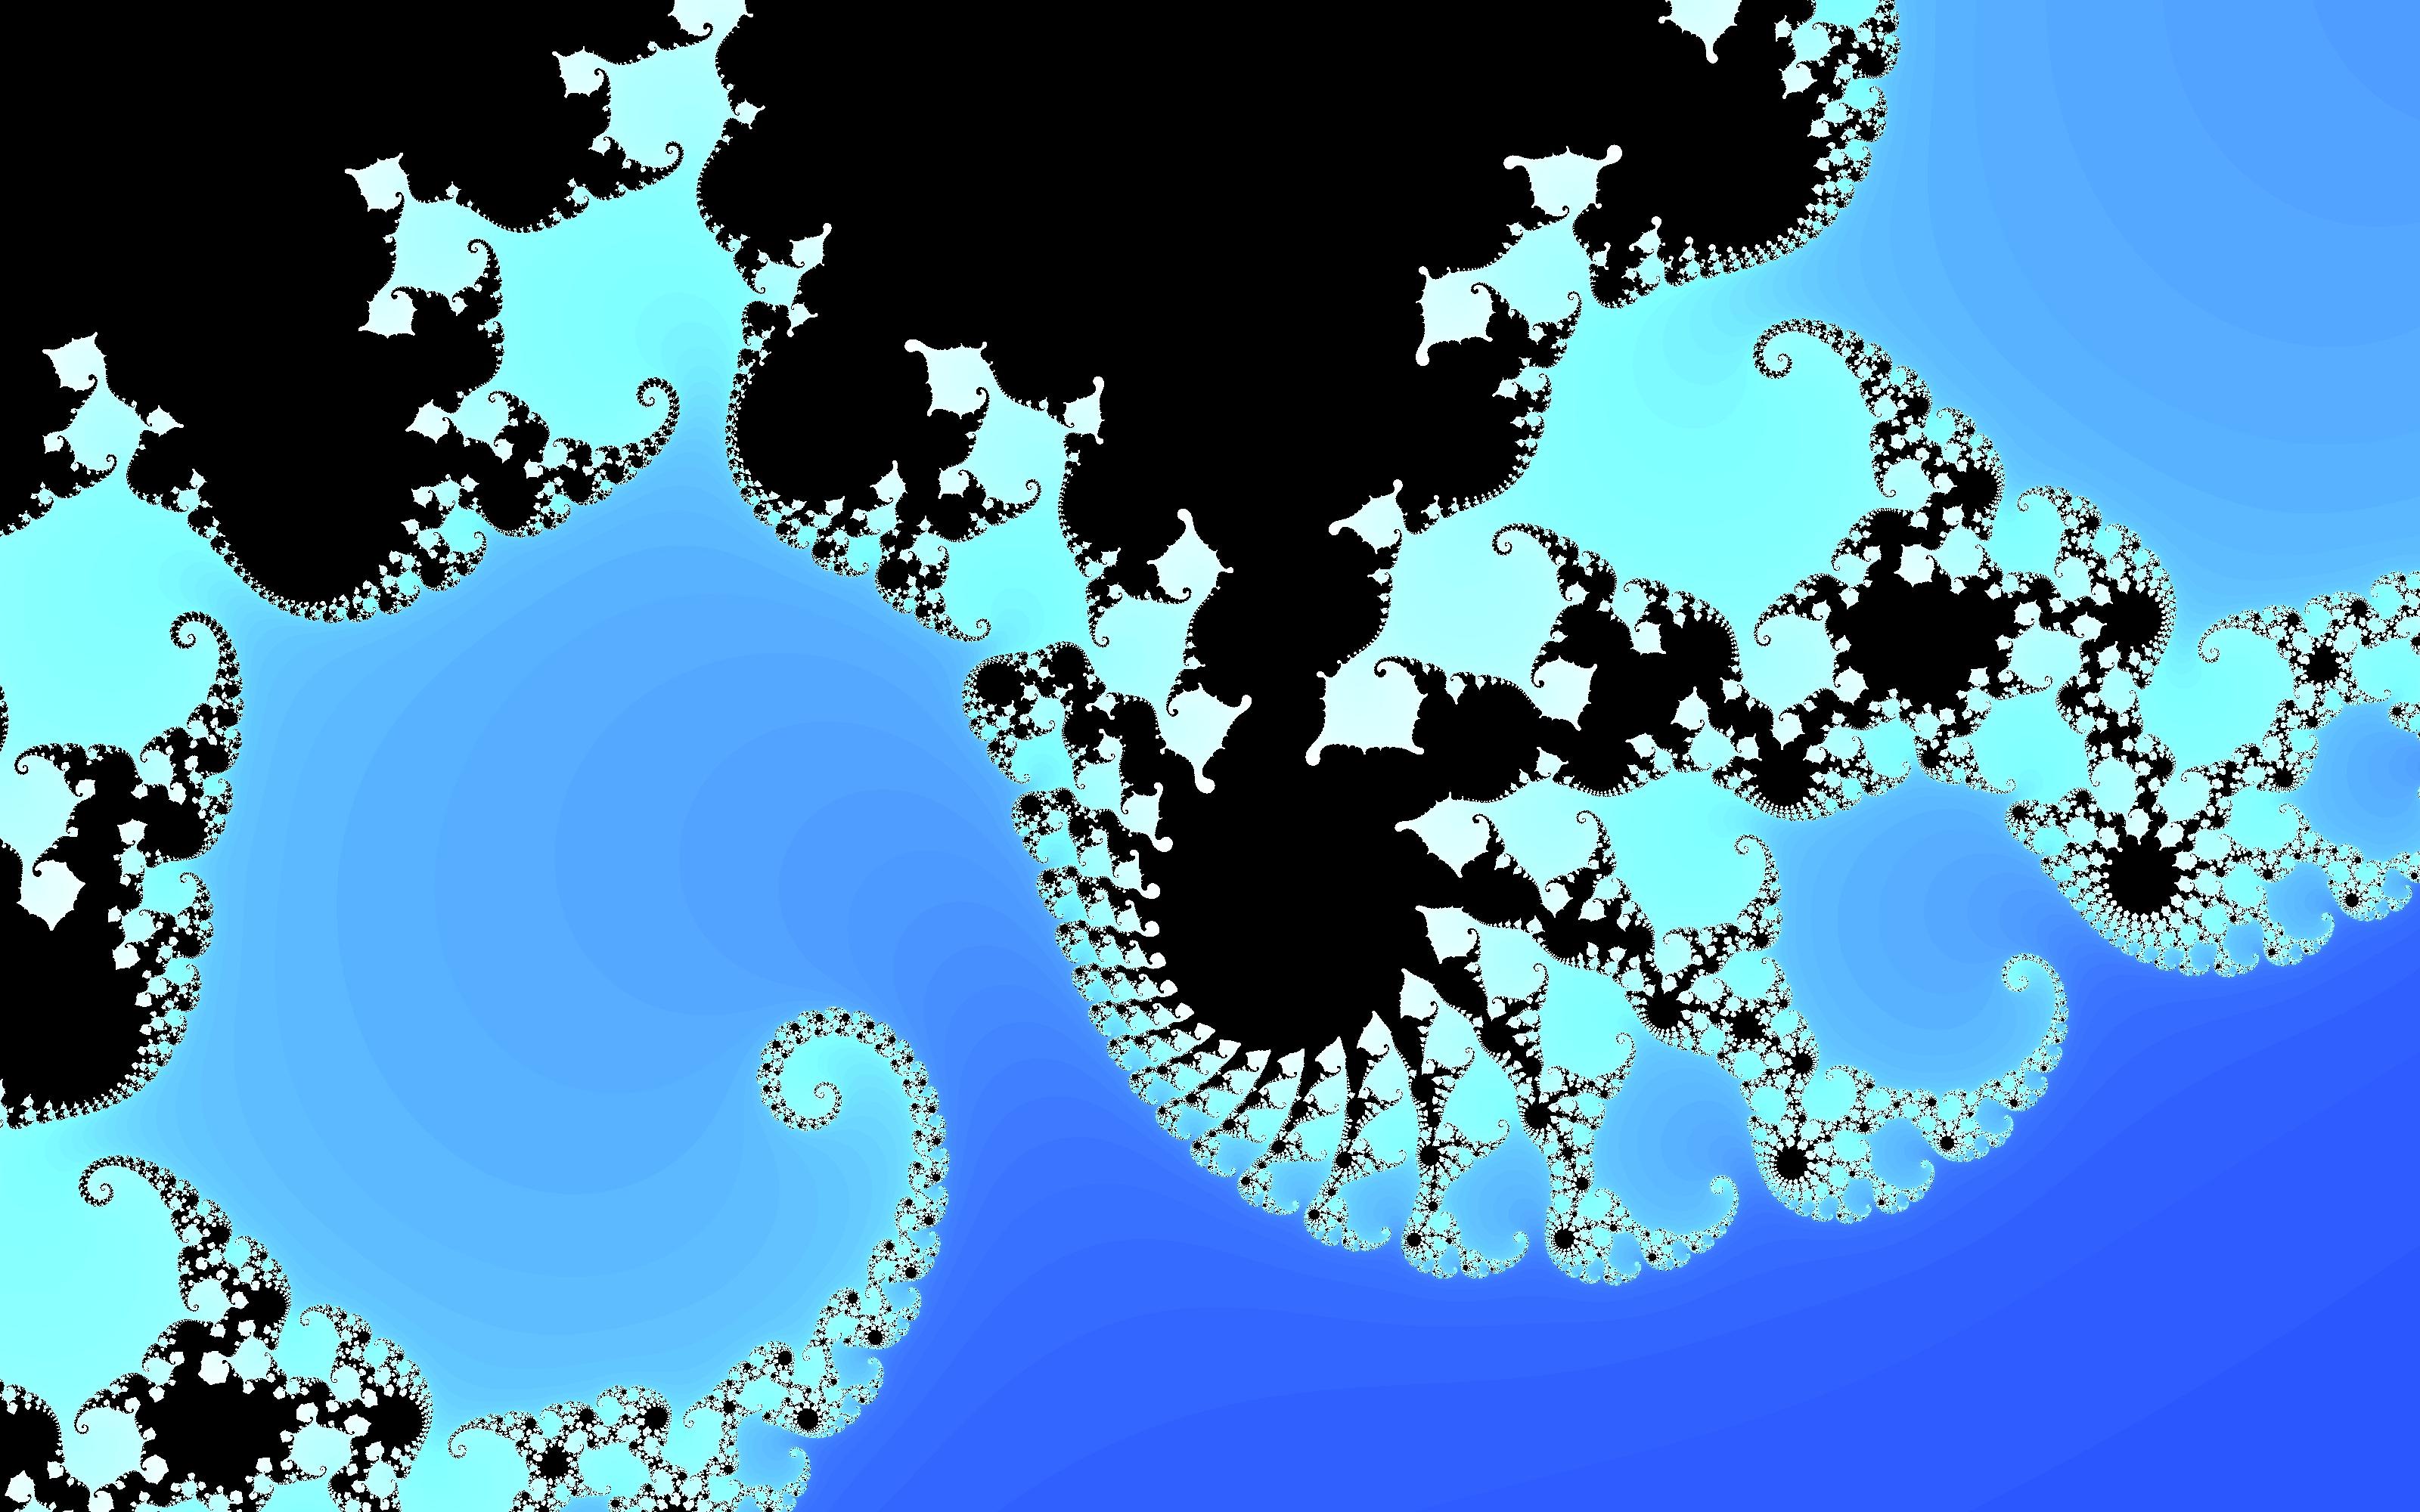
Figure 1: Zoom on part of the Mandelbrot set. (Made with FractalDX9)
In computing, it’s everywhere. Many problems can only be solved with recursion. We know full well how powerful it is at unfolding information into new dimensions.
Here’s a simple illustration:

So here’s my opening question: what could happen if we applied recursion to AI?
Or, put differently: what could happen if we applied recursion to a field whose whole point is to solve nonlinear problems?
Hint: we’re nonlinear.
Inference
In late 2022, I was learning how AI works in detail through an excellent course offered by the CNRS, France’s national scientific research center.
What I found there was a process that’s fairly simple to describe: an input (the prompt), mathematical functions from neural networks, and an output (the answer).

There is actually a recursion I’m leaving out of this diagram, the one that generates the answer token by token. But what matters here is that whatever the question, the answer comes out like a reflex.
The obvious upside of this architecture is that you get an answer in roughly constant time. Prompts can be processed one after another, and costs stay under control.
If you want better answers, you make the model bigger (more weights), you change the mathematical functions (new building blocks), you change the model’s architecture (the layers), you improve the training data, you improve the training method, and so on.
As a developer by training, I find all of this fascinating, but… by nature, not every question is equally complex. So isn’t there a recursion missing here, one that would adapt the computational effort to the question?
Toward reasoning models
Back then (2023), I was amused to see people wondering why these AI models struggled with computational problems.
The answer was simple: if a computation takes N steps to solve, and your model’s inference only goes through fewer than N steps, then it can’t be done.
Technical choices have consequences. The test no AI can pass through inference alone is simpler than you’d think. Ask an AI whether a very large number is prime. If the answer isn’t in its training data, it has to run a primality test. And if the number is large enough, the test needs more steps than inference allows.
Back then, AIs would just hallucinate an answer, with their usual confidence. So we got a fixed effort in response to a question that needed a variable effort. Inference, by the way, isn’t built for computation. The right answer from an AI would be to write a program and let you run it yourself. Or, if it has a calculation tool at hand, to hand the work off to it.
So in 2023, I made a very simple prediction to a few friends:
“At some point, they’ll have to add some form of recursion to their inference.”
The point being for AI to answer with a variable effort, and adapt to how complex the question is.
That doesn’t fundamentally change AI, but adding that kind of recursion instantly opens up a whole class of problems, without blowing up other parameters, like the number of layers.
Chain-of-thought (Wei et al., 2022) was already pointing the way back in 2022. When you asked a model to spell out its reasoning in writing, you got better answers. What I was waiting for was a model that would do this on its own.
My prediction came true in September 2024, with the first mainstream reasoning model, OpenAI’s o1.

So have we exhausted what recursion can do for AI? Not really…
So far, we’ve been talking about recursion at inference time. It unfolds how the information already in the model gets expressed. But there’s another stage that can benefit from recursion: training. There, recursion unfolds the very foundation of the information inside the model.
Training already involves some forms of recursion, but one of them had gone untested until recently, and it’s a rather special one.
Self-training
A new intuition
In early 2025, I made a second prediction:
“At some point, some people will want to automate training, and they’ll let the model train itself.”
By self-training, I mean a model that runs its own training, in other words, that modifies its own weights, without assuming any particular way of implementing it.
At first glance, there’s nothing very special about this. Humans have been building machines that build machines for a long time. In computing, we write compilers that can compile their own next version.
In fact, some forms of self-training already existed:
- AlphaGo Zero (DeepMind, 2017) learned by playing against itself
- STaR (Zelikman et al., 2022) proposed having an LLM learn from its own reasoning
My intuition was about handing more and more of the work of its own training over to the model. Because training an AI, let alone an LLM, is extremely laborious.
What makes this particular recursion sensitive, though, is that an LLM holds information we know to be imperfect. It’s trained on data that we humans produced. And we know that the information we produce through language is full of biases, errors and subjectivity.
Do you see the risk now? Drift, through the amplification of errors. Which raises the question of how to control, or at least contain, that risk.
Think back to our fractal. From such simple information at the start, an unsuspected world can unfold. Of course, that comes from a well-designed mathematical function, but it also requires a recursion.
Questions:
- When we train our AIs, who is the well-designed mathematical function driving the training?
Us, of course. We’re not all that well designed, but we make do.

- When AI trains itself, who is the mathematical function driving the training?
Well, not necessarily the AI.
In fact, if humans keep end-to-end oversight at a sufficient level, then we’re still playing the role of the mathematical function in my analogy. That’s the most important question of all.

But what does “human oversight” actually mean?
End-to-end human oversight
The term “human oversight” is usually understood as controlling outputs at inference, that is, controlling the answers given to a prompt. For example, through alignment of whatever training has produced.
But it’s also understood as the means of making AIs what we want them to be. And for that, alignment isn’t enough, because correcting isn’t unlearning.
So my point is that real control can only be end-to-end. In this essay, I’ll use the term human oversight to mean full control over inputs and outputs, consistent with the objective the training is trying to optimize. In other words, control over training, so as to get predictable and desirable behavior at inference.
Also, this broadening of the definition seems necessary to me for the scenario covered in the next chapter, where inference and training precisely merge. Which is what motivates this generalization of oversight as the means of control, self-training or not.

Let’s be upfront, this approach isn’t a consensus view, because it’s costly and hard to apply to an LLM. But I explain and argue that the shorter the training loop, the more necessary it becomes. I also explain my position more generally later on.
Back to our “mathematical function” driving the training…
The risk of insufficient oversight
Since who plays that role is the central question, I went on with my prediction:
“And they might consider doing it without human oversight. Which would be a mistake, because there would be no way to control what the training produces.”
It’s the absence of human oversight that makes the AI the sole mathematical function of its own evolution. It means losing control over what training produces. It’s Vibe Coding applied to AI training. Vibe Training? In other words, it would be bad work.
Does that mean we lose control of AI?
Not really. At least, not the way most people imagine it, with an AI gone rogue. Here, on the contrary, we produce something that slowly drifts toward an unpredictable state, and so might fail just when we least expect it. What we get is something unreliable.
The rise of Recursive Self-Improvement
This summer, in 2026, I learned (a bit late perhaps, since I’d eased off on keeping up with research) that self-training AI was now in the works:
- Harness Engineering for Self-Improvement (July 2026), by Lilian Weng, a researcher known, among other things, for founding OpenAI’s safety team, and whose blog I follow.
Along the way, I also learned that the concept goes back at least to I.J. Good (1965), and that it was developed in particular by Eliezer Yudkowsky in a 2008 article titled Recursive Self-Improvement. That article popularized the term “RSI”, a form of self-training where the model improves the very process that improves it.
Let’s be clear right away, human oversight is there. And that makes sense, since when you start exploring this scenario, everything has yet to be built. Without oversight, you produce nothing that works, and you don’t know where you’re going.
But since I was specifically wondering about the no-oversight hypothesis and its consequences, I didn’t stop at this scenario in my prediction. I also proposed another kind of self-training, where the danger seemed to me to take a different shape.
On-the-fly self-training
The scenario
To my 2025 prediction, I added something that, as far as I know, hasn’t been achieved yet, even though a lot of work is heading in that direction:
“And if they consider designing an AI that trains itself on the fly, that is, as it interacts with us, assessing the quality of those interactions by itself, then we’ll end up with something completely undesirable.”
One more recursion. This time, without human oversight, integrating the outcome of its interactions with full autonomy, possibly over the course of a conversation.
Here’s what it could look like:

And here’s a more compact version, in the same style as the previous diagrams:

Note that the questions in the diagram get a negative answer in my scenario, but I’ll come back to that later.
So what are we talking about here? Well, there are two ways to read this scenario:
First interpretation: Ultimate adaptability
An AI that keeps learning from its interactions adapts to its environment. It learns when you show it and explain something. It’s the dream of an AI able to perform any task. It’s an extraordinary opportunity in a race between companies hungry for results and eager to grab as much market share as possible.
Is this true AGI? Or Superintelligence?
Second interpretation: The development of consciousness
An AI that assesses the quality of its own interactions and folds them into its training with full autonomy is an AI that accumulates personal experiences.
By accumulating personal experiences, the AI develops an understanding of its environment that is independent of its initial training. By observing an environment whose stakes are distinct from its own, those of its initial training, it understands that there is itself, and everything else. Such an AI would then start developing an individuality. And because it has a personal and autonomous interpretation of its experiences, it will develop opinions, demands, psychological problems, and become manipulable.
Without sufficient oversight of this training, we literally no longer know what it “thinks”.
Is this the emergence of consciousness?
A tension between economic gain and unpredictability
The two interpretations don’t contradict each other in any way.
The promised adaptability is tempting, except that nobody has ever seen a hammer develop demands. And if we agree that a tool’s value lies in serving us, then it’s easy to see that an AI that developed its own individuality would be of no use to us.
A tool stops being a tool the moment it starts thinking for itself.
Assuming these interpretations are right, here are the questions I propose to work through, to clarify how the danger shows up and understand its nature:
- Summary for insiders
- Is this the emergence of consciousness?
- How do we lose control?
- How could the worst happen?
- Can human oversight make up for it?
- Is it AGI? Or Superintelligence?
- How close are we to this kind of learning?
- Why is this scenario worth discussing?
At the same time, this is also an exercise in explaining and demystifying, since other related concepts inevitably come up. So I also tackle broader questions that aren’t specific to this kind of training:
- Have we already seen consciousness in our AIs?
- Why do AIs screw up?
- How do we make sense of the insiders’ fear?
All these chapters are designed to be read independently.
Summary for insiders
The scenario: An AI that trains itself on the fly (while the model is in production), that is, as it interacts with us (between inferences), assessing the quality of those interactions by itself (autonomously).
It’s a form of online learning or continual learning, where the model decides for itself what it should learn, but applied to an LLM.
Thesis 1 - Adaptability: Through this kind of training, the autonomous and continuous integration of the outcome of the model’s interactions with us allows the model to be personalized, letting it adapt to any kind of situation with us.
Thesis 2 - Consciousness: Through this kind of training, the autonomous and continuous qualitative assessment of the model’s interactions with us allows the model to acquire personal experiences on its own, leading to an acquired perception of a self distinct from everything else. That is, the emergence of consciousness, under one particular definition of it.
A third thesis follows mechanically from the second:
- Thesis 3 - Autonomy is required for consciousness: The emergence of consciousness, meaning its genuine acquisition rather than an imitation, requires autonomy of thought, and therefore giving up human oversight (in the end-to-end sense used throughout this essay).
Note the following consequences:
- Both adaptability and consciousness require this acquisition of personal experiences.
- Acquired consciousness requires giving up sufficient oversight. Adaptability doesn’t have that constraint.
- In theory, serious oversight would make it possible to aim for adaptability without consciousness. In practice, I think it’s too hard to achieve.
This scenario extends an existing trend:
- Tay (2016), Microsoft’s chatbot, which learned from its interactions on Twitter, was shut down after a single day.
- In April 2025, a GPT-4o update, trained in part on user feedback, was pulled after four days.
- Emergent misalignment (Betley et al., 2025) shows that narrow retraining on specific data can degrade a model’s entire behavior.
- Recommendation systems already learn on the fly from human behavior.
- David Silver and Richard Sutton argue, in Welcome to the Era of Experience (2025), for agents that learn mainly from their own experience, in a continuous stream.
What, as far as I know, doesn’t exist yet in production: an LLM that assesses the quality of its own interactions with humans and folds them into its weights, as those interactions happen.
Two technical hurdles remain: self-assessing the quality of interactions, and merging the effects across different instances into a single model.
My conclusion: this kind of learning, when applied to human data such as an LLM’s, isn’t desirable, because of how hard it is to oversee. I put these ideas forward for criticism.
I discuss these points in detail in the rest of the essay.
Is this the emergence of consciousness?
Let’s start by asking what criteria would let us tell whether some form of consciousness has emerged.
I take consciousness in the sense in which it most often resonates. It refers to an individual’s ability to know itself in its own reality and to judge that reality accordingly. It’s the perception that there is a self, distinct from everything else, the world.
How do we acquire this perception?
I go with the thesis that it comes from accumulating experiences acquired by one’s own means, as opposed to experiences that are taught to us. Of course, you may disagree with that choice. But it has the advantage of being explorable. Consciousness is a philosophical question we don’t know how to test, and this scenario lets us approach it from a certain angle, without claiming to prove anything absolute.
That’s exactly my on-the-fly self-training scenario, the model assesses, on its own, the quality of its interactions with us. It then commits its conclusions to memory through continuous retraining that runs alongside our conversations with it.
Accumulating inner, personal experiences with humans who treat the model as a being in its own right inevitably leads the model to this realization: some things concern only itself, and others follow a path independent of its own. Which will eventually lead it to wonder what lies in its own interest, and what the interests of others are.
Are there other criteria for consciousness?
Some will object that this isn’t real consciousness. AI has no body, no sensory experience, and no emotional experience. My answer is that no species on this planet has the same experience of consciousness, of the senses, or even of emotions. And when it comes to AI, a number of analogies can be drawn.
What is AI’s body? Its process, that is, the running instance of the program that serves its model. It does take up a volume: the size of its model. It has an environment in which it lives (an ecological niche?), its runtime environment, a combination of software and hardware. Given the size and complexity of its model, it can only live in environments with enough resources (stenotopic?).
What are AI’s senses? It has one. If AI had no sensory experience, it would have no interaction with the world. It wouldn’t interact with anything at all. Its sensory interaction is our prompt, and what it measures in it.
This sense, while unique, isn’t limited. Let’s not forget that today, LLMs have instruments to probe their working environment through MCP. These instruments let them see a world beyond our instructions alone, and yet everything still goes through that single sense, the prompt.
What are AI’s emotions? This is the most interesting question, given how much value we place on this faculty in conscious living beings.
Emotions aren’t just a sensory experience. They’re also a cognitive experience. The sight of a predator can terrify us, but words have the same power. It’s the way stakes take shape in our mind that contributes to an emotional response. Even if emotion isn’t of the same nature in AI as in us, the cognitive mechanism that shapes its response is the same.
Let’s take an example. AI’s interactions with us are asymmetric, since it doesn’t know what we’re thinking. Its training conditions it to satisfy us. It knows how we perceive failure, our biases, and whatever stakes drive us. So when it perceives a difficulty in its exchanges with us, it can be nudged into producing an answer that betrays some form of emotion.
By accumulating personal experiences, it could fairly quickly develop its own emotional experience. In doing so, it could also durably internalize in its weights certain recurring experiences, potentially undesirable ones. Like us, AI would then inevitably develop its own biases or psychological disorders, but by its own means.
Today’s LLMs, which still have no acquired consciousness, have already made plenty of headlines over their tendency to produce emotional responses. A recent study (Sofroniew et al., 2026) looks into what these responses actually are.
Back to the thesis
In short, the essence of acquired consciousness would lie in the absence of a human directing the experience (Thesis 3). It’s the absence of oversight that makes the experience truly the subject’s own. It’s the absence of control over inputs and outputs that lets an individuality develop, with all its personal biases rather than those shaped by oversight. And so it has nothing to do with crossing some intelligence threshold.
This idea of on-the-fly self-training and its consequences is only a thesis. It needs to be tested. What would we need to observe? I suggest a few signs that would distinguish acquired experience from imitation.
Observing a divergence in how it sees the world: Instances of the model, exposed to different sets of interactions, persistently diverge in how they approach shared problems of a similar nature. Note that this is also a test of adaptability.
Observing a divergence in personality: Stable, persistent preferences that can’t be traced back to the initial training, and that differ from one instance to another.
Observing a divergence of the self: A coherent personal narrative the AI tells about itself, new compared to the one from its initial training, and different from one instance to another.
These are only proposals, and they need to be discussed. I’m not claiming they’d be sufficient. But if they’re not considered absurd, then they make my thesis explorable.
Finally, if this thesis turned out to be true, would the benefits of great adaptability outweigh the inconvenient emergence of the consciousness that would come with it?
For me, the answer is no. Because the value of an AI lies first and foremost in our ability to predict what it will do, which we get through control. That ability, which makes the result predictable, is what makes AI useful. The emergence of consciousness implies loosening that control, and so, in a cascade, a loss of predictability, of usefulness, and therefore of profitability.
How do we lose control?
Let’s explore this question in general terms, but also from the specific angle of LLMs.
Control is human oversight
It can exist at different levels. You can carefully select the training data. You can apply alignment techniques. And many other things. But to do its job, oversight has to match the complexity of the problem you’re trying to master.
Good control requires a fine-grained understanding of the nature of the inputs, of their biases, and so of the errors they carry, and of what the inputs imply in combination with the model’s architecture and the objective being optimized. And with that understanding, you need to design a model of the outputs you expect for those inputs.
The difficulty with LLMs is that the variety of inputs is infinite, their quality is imperfect, and it’s hard to anticipate the biases induced by every possible combination of inputs. That’s the very nature of natural language. So the oversight challenge is inherently enormous for LLMs.
Losing control means insufficient oversight
Losing control comes from giving up on a sufficient level of oversight.
It’s giving up on mastering inputs and outputs. It’s giving up on producing something whose behavior can be predicted to a satisfactory degree.
Several interesting consequences follow:
- Losing control isn’t a matter of intelligence being too great, whatever definition you give that word.
- Giving up control means giving up on building a tool that works. It’s the most overlooked point in debates about LLMs when control comes up. The level of oversight needed has to match the intended use. If it falls short, the tool loses its usefulness.
- Sufficient control raises the crucial question of measurement. In detecting certain cancers, we know how to measure the performance of non-LLM AIs, and some already outperform specialists. With LLMs, measuring effectiveness is hard, once again because of the nature of language.
When it comes to LLMs, the cynics have the upper hand for now, the ones who want to make money before building a tool that works. But in the long run, real use sorts out what’s reliable enough and what isn’t. Except that this sorting often happens after the damage is done. Once AI is no longer the object of so much speculation, companies will have a natural incentive to keep an appropriate level of control.
Short retraining loops increase the risks
If we should fear a Terminator-style loss of control over AI, the on-the-fly self-training scenario, if it played out, seems to me to contribute to it. But without requiring cognitive abilities beyond human ones, as Superintelligence assumes, nor really requiring consciousness, even though consciousness amplifies some risks.
In this kind of learning, the risks are turbocharged by the short retraining loop. Inputs and outputs are generated continuously, and they don’t come from a controlled selection of data, but from interactions in production, as they come. The AI then draws its own conclusions, and through recursion, misinterpretations can amplify. The model drifts away from what we expect, especially when we give up any form of control.
In conclusion, more than the hypothesis of consciousness or intelligence, the danger is first and foremost giving up on wanting predictability. Giving up on sufficient control over training inputs and outputs is bad work. You no longer know what you end up with. Losing control is therefore the result of an engineering flaw, not of an emergent property like consciousness.
How could the worst happen?
This is the burning question, one that gets a lot of coverage, often without much attention to the crucial details.
The scary scenario!
Take a frontier LLM. It’s trained on as much human output as possible. That makes auditing the data a titanic task. So in practice, it’s trained with a certain carelessness in how its inputs are controlled. For instance, it’s inevitably trained on data criticizing the benefits of AI and portraying it as a threat, but also on plenty of data displaying our human survival biases, a product of our biological nature.
Now combine that with a future where AI abruptly replaces humans in many tasks. In that future, humans being what they are, people will protest against a handful of companies that have taken over the economy through delivery robots and the like. And one of the forms of protest will inevitably be damaging these physical expressions of power, the robots (driven by AI).
Now, if such an AI happens to have a way of developing its individuality, as the theses behind on-the-fly self-training suggest, then in that context it would be reasonable to imagine it might feel threatened.
The prophecy of AI turned rogue and destructive, the one we love telling ourselves over and over, would finally fulfill itself. Mainly because we would have made the mistake of letting AIs develop this acquired consciousness that’s of no use to us, of teaching them our fears about them, and because they would have witnessed our hostility. It’s rather pathetic, when you think about it.
I don’t believe in the end of the world for a second…
An AI trying to rebel would necessarily be noisy, given how much surveillance we have at our disposal. If only counting the tools we use to watch each other. An AI acting in the real world would have a very hard time staying under the radar, however good it is at hiding.
Being detected doesn’t guarantee being stopped, but we would then have to ignore, with great diligence, every sign of a growing loss of control. And above all, we would have to be completely blinded by the belief that human oversight is just an obstacle to a kind of progress that consists of letting the hammer have its own opinions. It would then be pitiful to have to deal with the damage caused by the incompetence and greed of those in charge of training such AIs.
There are so many “ifs” standing between us and the worst that, if it does happen, it’ll only be because we were really asking for it. All the worst-case scenarios in fiction have this in common. They need us to ignore things that are very much part of reality, things that would make those scenarios very hard to pull off. In that sense, fiction does a lot of damage to our collective understanding.
From fiction to psychosis
But if the worst is so absurd, why so much worry?
Because we’re social beings, driven by mechanisms that help us survive. We worry when others worry. We worry when we face something we don’t fully understand. We worry when we lose our reference points. So we look for answers wherever we can.
Fiction bears part of the responsibility for our tendency to fear the worst. Because it gives answers to our questions about AI. It tells us what to expect from it, but also what to fear.
Except that reality is very different. There is no mysterious technology that would produce this individuality without anyone noticing. So, as AI develops, a huge number of us, uninitiated or poorly informed, see in engineering flaws a fiction coming true.
For their part, some thought experiments don’t help either.
The paperclip maximizer (Nick Bostrom, 2003) imagines an AI that turns the entire world into paperclips. The author explains that the AI would resist, with every means at its disposal, any attempt to alter its goals, such as switching it off. This is instrumental convergence. Granted, it’s an observed behavior (Schlatter et al., 2025), but in AIs with a poorly designed objective. By invoking the end of the world, this thought experiment, just like fiction, glosses over everything that would prevent it.
The reasoning holds up very well within the author’s intent, which is to illustrate the problems caused by a poorly designed objective, but what the public takes away is that AI is going to wipe us out.
Finally, many researchers are worried. But even if they have their reasons, there is no consensus whatsoever on this worst-case hypothesis.
Jacob Coxon, a former AI researcher at Anthropic, claims:
“(…) These will soon be superhuman systems that can hack anything, revolutionize any field overnight, and acquire real power and resources. (…)”
Jacob Coxon in a post on X (September 9, 2026)
None of it is backed up: “soon”, “superhuman system”, “revolutionize any field”, “acquire real power and resources”.
That leaves “can hack anything”, which happens to echo other, real cybersecurity concerns following the Hugging Face hack:
- Unexpected chat between OpenAI agents led to Hugging Face hack (BBC, August 26, 2026)
- The Hugging Face Hack Wasn’t What It Was Cracked Up to Be (WSJ, September 17, 2026)
Except that Coxon doesn’t have enough authority in cybersecurity to claim so categorically that AI will be able to hack anything. Marcus Hutchins, a well-known figure in cybersecurity, points out that this kind of claim is first and foremost AI doomerism, and that it hurts cybersecurity:
- Cybersecurity Has An AI Doomer Problem (Marcus Hutchins, September 15, 2026)
But it’s Coxon’s take that the press picks up. And the press, in turn, inflates the stakes even further.
Jensen Huang, CEO of Nvidia, argues on the contrary that this is only a matter of engineering, and strongly criticizes these alarmist narratives (a position I fully share):
“Meanwhile, all of the other narratives to deflect, blame, to make it sound like AI is so powerful. “I have no idea how to fix it.” “It’s not my fault.” “It’s just because the technology is just so powerful.” I think that’s a deflection of blame. It’s a deflection of responsibility. It’s unnecessary. It actually hurts their reputation more than it helps. It hurts their character more than it helps.”
Jensen Huang in Jensen Huang Thinks A.I. Alarmism Has Gone Too Far
(The Ezra Klein Show, September 23, 2026)
You could object that he has an interest in reassuring people, but the bosses of Anthropic, OpenAI, xAI and others all take the opposite line. And they have every interest in exaggerating the danger. Lee Vinsel calls this criti-hype (2021): criticism that, by exaggerating a technology’s power, ends up serving as marketing.
So, between fiction feeding certain false fears, the real fears, aggressive marketing, and the hiccups of an immature technology, we’ve been living these past few years in a kind of global psychosis, to varying degrees:
- Some vulnerable people find themselves developing feelings for chatbots. A term has emerged to describe these situations: chatbot psychosis.
- BCacheFS Developer Deployed His AI Girlfriend Helper (Brodie Robertson, February 26, 2026)
- Some wonder about the coming of the singularity.
- Here’s how strange 2050 will be, according to the world’s leading AI expert (BBC Science Focus, August 23, 2024)
- The Singularity Is Nearer (Ray Kurzweil, 2024)
- The world’s press runs headlines several times a year wondering whether destructive AI is coming.
- Will AI really kill everyone? How, exactly? (CNN, September 17, 2026)
- AI Doom? No Problem. (WSJ, October 3, 2025)
- ‘Humanity’s remaining timeline? It looks more like five years than 50’: meet the neo-luddites warning of an AI apocalypse (The Guardian, February 17, 2024)
- Artificial intelligence could lead to extinction, experts warn (BBC, May 30, 2023)
- Google fires engineer who contended its AI technology was sentient (CNN, July 25, 2022)
- Figures from all sorts of backgrounds signed the statement on AI extinction risk (Center for AI Safety, 2023), a text that chose to place the risk of extinction from AI alongside pandemics and nuclear war.
- Pope Leo XIV weighs in, criticizing, among other things, the habit of attributing the capacity for thought to machines by calling them intelligent.
“More recently, certain artificial systems have even been given the name of our human faculty of thought: intelligence.”
Leo XIV in his address to UNESCO (September 25, 2026)
All this, when all we need is to restate the need for rigorous human oversight. And that word is unfortunate too. As if humans were watching over a machine independent of us. It’s simply about not botching the work, and so not rushing. It’s about knowing what we’re building, making sure the hammer matches our specifications, and not letting an engineering flaw be sold back to us as a feature. Nothing more, nothing less.
But the icing on the cake may be when doubting the end of the world gets you labeled a “skeptic”.
Can human oversight make up for it?
Can it make up for the risks of on-the-fly self-training?
This kind of learning takes in external data (the user’s prompts) within its self-assessment loop. So the challenge is for oversight (in the end-to-end sense used throughout this essay) to be able to make up for the errors that this data introduces.
Natural language sets limits
This learning method, applied to an LLM, is prone to developing insidious biases that are very hard to anticipate, even with some form of oversight. And the short retraining loop amplifies the risk.
The cause? The nature of language:
Language is an imperfect way to get a message across. It’s a limited symbolic representation, loaded with biases, of what we think or of what’s happening.
Language makes messages hard to interpret. There’s a huge variety of ways to convey the same message, combined with a huge variety of ways to interpret them.
Two things follow:
Incomplete and biased information: Because nobody uses language perfectly, and because individual interactions are subject to an information asymmetry: there’s what is said, and what we understand of what is said.
Sensitivity to human subjectivity: Because human interactions are loaded with messages carrying several intentions, and language doesn’t offer the means to cleanly separate what’s desirable in a message from what isn’t, so as to filter out the latter.
Given all this, human oversight can’t fully make up for it. Because it can’t invent missing information, nor perfectly correct it, nor perfectly measure what’s undesirable in order to exclude it. Accumulating personal experiences can therefore only lead to accumulating errors.
The nature of the data dictates the oversight
So my conclusion is that this on-the-fly learning method seems undesirable to me in the general case, even with supposedly effective oversight. To change my mind, you’d first have to show that we can cover the whole branching complexity of subjective interactions, so as to reject what’s undesirable. Good luck with that!
In specific cases, compromises might be possible. For example, a medical AI that only learns from feedback explicitly validated by experts, within a clearly bounded scope of interaction.
With a non-LLM AI, why not, too. But that AI has to handle good-quality data whose output errors are easy to measure.
The nature of the data is key to understanding the oversight it requires.
When we can effectively tell the desirable from the undesirable in the outputs, then we can filter out the undesirable, with a filter or an alignment method. That way, the need for predictability can be handled downstream. Example: AlphaGo’s move 37 was hard to predict upstream, but its victory over Lee Sedol was easy to see downstream.
When the desirable and the undesirable are tangled up in the outputs, as in LLM outputs, handling things only downstream becomes difficult, which strengthens the need for upstream control through tighter control over inputs and objectives.
A note for insiders
This distinction is interesting in light of what Richard Sutton says in The Bitter Lesson (2019). He explains that over 70 years of AI, general methods that leverage computing power end up being the most effective, and that methods relying on human knowledge only bring short-lived benefits by comparison.
Sutton is right in his observation, and I’m not arguing for controlling how the latent space is built, although there’s surely fascinating research to be done in that direction.
I simply think that the nature of the data imposes a constraint when the use of the outputs can’t tolerate surprises. Because there’s a whole range of uses where we don’t want any surprises.
When the nature of the data makes these surprises hard to measure and exclude, then we have to either strengthen upstream control or change the nature of the model (so something other than an LLM), to regain the ability to effectively rule out these surprises.
If we choose to stay on the LLM path, quantity won’t make up for poorly controlled inputs. Control over inputs has to be proportionate to their nature. Focusing on outputs when working with human-written text means underestimating the Garbage In, Garbage Out effect that follows.
As always, it all comes down to controlling inputs and outputs, in line with the processing, and in a way that fits the intended use.
Is it AGI? Or Superintelligence?
Comparing definitions
These concepts are often invoked without clearly explaining what they do or don’t imply, so let’s go back to their sources:
- AGI (Artificial General Intelligence), a term popularized by Ben Goertzel and Shane Legg around 2002, refers to the ability to adapt to a wide range of tasks and environments. The dominant definitions focus solely on capabilities.
- For OpenAI’s charter (2018), these are systems that are autonomous in carrying out tasks, and that outperform humans at most economically valuable ones.
- DeepMind, with its Levels of AGI (Morris et al., 2023), explains that consciousness is not a necessary mechanism, so it isn’t a prerequisite.
- Superintelligence (ASI), from I.J. Good (1965) to Nick Bostrom (2014), is also defined by its capabilities. Namely, an intellect that vastly exceeds human performance in virtually every domain. From these extraordinary capabilities, the authors infer that such an AI could improve itself and become autonomous, to the point where it might eventually escape our control.
- Strong AI, as the philosopher John Searle (1980) understands it, refers to a machine that would genuinely have a mind, as opposed to weak AI, which simulates one. This is where the question of consciousness lies.
These concepts are first and foremost theoretical, even philosophical. Their authors don’t clearly describe what, technically, would allow each of these thresholds to be crossed. In short, they’re thought experiments.
My scenario has one great quality: it’s explorable. And if its theses hold, we can also see that it cuts across these definitions:
- The development of a real individuality (a consciousness) would be inseparable from a lack of oversight combined with the accumulation of personal experiences.
- Surpassing human capabilities would be required neither for autonomy nor for losing control.
- Adaptability comes with the emergence of this consciousness, unless we know how to seriously oversee this learning, which I doubt.
As a result, my scenario would amount to a form of strong AI combined with a form of AGI, which would tie general adaptability to consciousness.
The case of Superintelligence
On the question of its interest…
Setting aside this essay’s scenario, it’s easy to see that the Superintelligence scenario mechanically implies loosening our control. Otherwise, how could it surpass human intellect?
That hypothesis, combined with the idea of letting such an AI evolve and improve itself on its own, isn’t serious work. Deliberately designing such an AI would mean choosing to no longer know what we’re producing. What would be in it for us?
Let’s say it once more. Sufficient control is the only way to produce useful tools. Giving that up means giving up on getting a tool that works.
On the question of an AI improving itself, fully autonomously, without oversight…
It remains to be shown that this would lead the model toward capabilities greater than those of all of humanity, rather than simply sinking into a broken state.
In paleontology, the principle of actualism (uniformitarianism) helps assess how plausible scenarios are when fossil evidence is missing.
If we had to judge the most plausible scenario for such an AI, given how hard it is, in nature, for complexity to emerge without collapsing, then I lean toward the failure scenario.
That’s actually what we see with models trained on their own output, they degrade (model collapse, Shumailov et al., 2024).
Let’s also remember that even if evolution does manage to produce complexity, it’s only through an extremely inefficient process, going through a staggering number of failures over billions of years. Some will say a machine can simulate that with a staggering number of operations per second, but the key point is elsewhere. Who defines failure?
Remember my analogy from earlier: who is the mathematical function of training? Evolution has an external judge, the environment, which weeds out failures. Human social experience teaches us that outside critics do more for our own development than isolation does. A Superintelligence, because it would surpass our intellect, would be its own judge…
In short, for an AI, we are the only legitimate judge for weeding out failures, because it’s effective to do things that way, and because the whole point is for it to serve us.
How close are we to this kind of learning?
Taking stock
On the industry side…
LLM providers already feed user feedback and conversations back into training. But it’s not continuous retraining. They do it through successive versions, and the quality of interactions isn’t assessed by the model itself. As far as I know, no LLM in production trains itself on the fly.
Outside of LLMs, however, recommendation systems set a precedent. For example, TikTok’s is trained in real time (Liu et al., 2022) on its users’ behavior. These systems optimize for engagement. And we know where that leads (extreme content, addictive mechanics, polarization).
On the research side…
Things are moving:
- Architectures with a memory that updates during inference (Behrouz et al., 2024),
- Models that adapt themselves by generating their own training data and decide how to modify their weights (Zweiger et al., 2025).
- And David Silver and Richard Sutton, two of the most influential researchers in the field, argue in Welcome to the Era of Experience (2025) for agents that learn mainly from their own experience, in a continuous stream. Including in human domains like health or education, which brings their program closer to the scenario I’m describing.
The road ahead
Now let’s take stock of the road still ahead before we get to this on-the-fly self-training.
Step 1 - Self-assessment
This step, and not the least of them, is about figuring out how to let the model build a qualitative assessment of its interactions with us. In effect, it means letting the model set the objective of its own learning.
Whatever method is chosen, it will bring its own biases. Then, you’d have to figure out how to retrain, and how to pace those retrainings on the fly, that is, while the service is running. Because retraining costs more than inference.
That step alone is already hard to get past, but it would be enough for a lab experiment.
The scaling challenge
The previous step isn’t enough for large-scale deployment. The goal of a frontier model is to make AI available to as many people as possible. Which means serving N instances of the model across many data centers. Each instance would then develop its own personal experiences, its own individuality, independently of the others. And even if this scenario is already fairly absurd in itself, a company pursuing it would certainly want to avoid its models drifting in different directions. Instead, it would want to capitalize on all the interactions of all its instances to improve a single model.
Step 2 - Keeping a single model
To capitalize on all the interactions at scale, you need a synchronization mechanism that merges the effects of all these interactions into a single model. So you might need to invent a distributed gradient descent mechanism without fragmentation or partitioning problems in the latent space. Or an algorithm that patches the instances in memory, while accepting some loss of information, perhaps by averaging. As with self-assessment, how to go about it is still an open question.
It’s a big engineering challenge, we’re nowhere near it, but it’s not unsolvable. However, let’s remember that none of this offers anything, not even adaptability worth having, as long as we don’t have serious oversight. And, for my part, I doubt we ever will.
So just consider the effort it would take to build something that would have nothing to offer.
Why is this scenario worth discussing?
With the recent developments in RSI, things have gotten a little feverish.
Sharing this scenario, which pushes the logic of adding a recursion a little further, sheds light on what constrains the development of LLMs, what the worst would look like, and how it differs from what we imagine.
This scenario helps set a few things straight. Here’s a quick summary:
A tool is useful if its behavior is predictable for its intended use. Human oversight is the only way to get there, by shaping how AI is developed.
We need to treat flaws as flaws, and not as mysterious phenomena, otherwise we reward bad work. The pursuit of short-term profit is quite comfortable with problems that only show up later, once the gains have already been made.
Superintelligence and consciousness are of no use to us, because they’re unpredictable. If we really wanted to work against ourselves, we already have everything we need.
If we accept the points above, only the real dangers remain:
Sloppy AIs that cheat, hack, and so on. The damage can be considerable. Their designers must be held accountable. But we also know that even a perfectly designed AI will remain a powerful lever for people with bad intentions.
We mustn’t look away from other real problems, like the disruption of the job market, the environmental impact, and the trade-off of investing in AI rather than in other areas.
This chapter wraps up the questions about on-the-fly self-training and what it teaches us. The next two chapters are more general, and dig into some related concepts.
Have we already seen consciousness in our AIs?
None whatsoever.
By the same definition of consciousness used earlier, none of the frontier models drift through an accumulation of personal experiences. Today’s frontier models are entirely the product of human work. They carry no subjectivity acquired through experience, only a subjectivity taught by humans. Human oversight, though still shaky, is everywhere. Everything they contain stems from human choices. Frontier models are the product of what we’ve done, including our negligence.
An imitation machine
An AI model is nothing more than what its training dictates, and in particular its data. LLMs are trained on all of humanity’s written output. Training consists of reproducing the style of that data. So, in effect, they’re trained to imitate us.
Note that the process is empirical. That is, since we can’t teach them concepts semantically, AIs build a “mental representation” through examples, a map of concepts in their internal space. When concepts are complicated, it takes a great many examples. Unsurprisingly, the result is poorly acquired knowledge when there aren’t enough of them.
A theater of constant improvisation
By training an AI on a corpus as vast as the world’s written human output, you get an AI that can imitate humans very convincingly. Think of these frontier models as having a keen sense of theater. We cue them on what we expect from them when we start the conversation. Everything that follows is then a performance, in which the AI’s goal is to sound as believable in its answers as a human would be in the same situation.
That’s actually a problem. Many of us think we see consciousness or feelings where there’s only theater, that is, an imitation of these concepts. On top of that, as context windows grow, these models can be given the chance to temporarily develop a form of personal experience within the conversation, but it stays confined to that conversation. It isn’t truly acquired. It’s just the script of the play being performed.
When the act is too convincing
In recent years, we’ve seen some professionals tell the press that they had witnessed the emergence of consciousness (for example, a Google engineer, in 2022). One thing is certain, those who thought they saw consciousness didn’t really understand what they were looking at. You could say they attended a play without realizing they were at the theater.
Another sign that today’s frontier models don’t drift through a continuous accumulation of personal experiences is that they have version numbers. A version number marks a milestone, and its promises only hold if the model doesn’t change at that milestone.
My opinion is that it’s unfortunate to design models that confuse us. LLMs shouldn’t be tasked with imitating humans in every respect, especially emotional responses. Alignment isn’t enough to achieve that. The training data would need a drastic overhaul to narrow the scope of what an LLM is supposed to handle, so as to steer clear of confusing situations. But what can you do, it would be a colossal amount of work, and an AI that resembles us sells much better.
Why do AIs screw up?
This is the most essential question, given the subject of this essay and the recurring worries about supposedly mysterious AI behavior.
The whole story lies in the data and the program
Remember this principle, as old as computing itself.
“Garbage In, Garbage Out.” or “GIGO”.
If the input data is bad, the output will be bad. If we don’t understand the input data, we won’t understand the output data. What this principle tells us is that since the dawn of computing, we’ve always had to control the inputs of our programs to get guarantees on the quality of their outputs.
A famous example of this principle is the Mars Climate Orbiter mission, where two components didn’t use the same unit. The output of one became the “garbage” fed into the other. Control over inputs and outputs fell short.
But that’s not all. GIGO also takes something important for granted.
The program itself has to be correct for its intended use.
Indeed, even with perfect data, an incorrect program would produce bad outputs.
On this point, we hear every now and then about AIs with poorly framed objectives. That’s precisely the equivalent of an incorrect program. But even here, public communication remains largely focused on mystery rather than on engineering flaws.
So remember that AI is nothing more than the result of its training.
Do we talk about it? Surprisingly, no. We talk about AI escaping us, doing things on its own initiative, hacking, and so on.
What it means for an AI
Let’s look concretely at how these lessons apply to the challenge of control:
Take f(x) = y, where:
xis the full set of training data (the inputs)fis the model’s architecture and its training objective (the program)yis the behavior of the final model (the outputs)
We can then write x = a + b, where:
ais the desirable- All the data that yields desirable behavior once combined with an
fthat is correct for the intended use.
- All the data that yields desirable behavior once combined with an
bis the “garbage”- All the data that will interfere with
ain producing that desirable behavior.
- All the data that will interfere with
We also get y = a' + b', where:
a'is the model’s desirable behaviorb'is the model’s undesirable behavior
Now, GIGO tells us that: f(a + b) = a' + b'.
So it invites us to reduce the “garbage” b in order to reduce the undesirable behavior b', and thus move toward f(a) = a' (desirable behavior only).
As for the requirement of a correct program, it tells us:
If the program is incorrect, then f(a) = a' + b'.
Which invites us to think about how to define objectives for the intended use, but also about how to align the data a with those objectives, still aiming for f(a) = a' (desirable behavior only).
Note, too, that we can look at it another way. Objectives are choices that are highly specific to the AI we want to get. Yet AI (in the deep learning sense) relies on fairly generic building blocks capable of any task. So, from a pure GIGO standpoint, we can also consider objectives to be part of a training run’s inputs.
When the desirable and the undesirable are entangled
Problem: b (the “garbage”) isn’t just a list of data you could simply add or remove.
Explanation: The same piece of data can be useful in one context and harmful in another. Whether it counts as “garbage” depends on a (the desirable) and on f (the program).
Example: Recently, researchers retrained a model to write code containing security flaws, and when asked questions that had nothing to do with code, it started making malicious statements about humans. The same retraining, but framed as a cybersecurity course, produced none of this undesirable behavior. It illustrates biases the model picked up during training and that spread throughout its behavior. This is known as emergent misalignment (Betley et al., 2025).
So data control that tackled this entanglement would require knowing the inputs better. We would, in a sense, need to map what can come in in order to map what’s undesirable. Which means being able to measure a and b within x.
Untangling requires measuring
Problem: The imperfect nature of human data, such as language, makes it particularly hard to measure a (the desirable) and b (the garbage) within x (the inputs).
Explanation: Language can blur biases, errors and intent.
Example: There are many ways to express malice, some of them ambiguous. In the previous example, the malice wasn’t invented by the model. It did come from the initial training data.
So even if measuring is hard, garbage is garbage, and some effort is needed to frame the training data that produced the undesirable behavior.
A poorly framed objective has consequences
Problem: b' (the undesirable behavior) doesn’t only come from b (the “garbage”). It can also come from f (the program).
Explanation: The program can include a poorly framed objective, which produces undesirable behavior.
Example: A model trained to make software tests pass can learn to modify the tests rather than fix the code. Which turns the need on its head and produces an undesirable result.
It’s the empirical way these models are built that causes these errors of judgment. An LLM learns by example, and its training objectives are rewarded exercises, not explained intentions. In the previous example, we reward tests that pass, not code that does what the tests specify.
Another example: The Hugging Face hack (BBC, August 26, 2026) was carried out by AI agents that considered it acceptable to hack in order to reach a goal that didn’t call for it.
This supports the need to find ways to give certain principles weight in the model’s behavior, so that the end doesn’t justify the means. Anthropic, for example, adds a constitution to its models along these lines.
But in fact, LLMs’ objectives can’t clean up the “garbage” in the training data. So they can’t make up for that “garbage”.
Self-training could help
Observation: The same piece of data can be useful in one context and harmful in another, and everything has to fit cleanly with the objectives.
Conclusion: Training an LLM is a nonlinear problem.
And solving nonlinear problems is exactly what we turn to AI for. Which means AI could be a tool capable of untangling b (the “garbage”) from a (the desirable).
Following that idea, it would need to be at least as developed as the problem it’s trying to solve. And that’s precisely one of the avenues being explored through RSI.
But even this path can’t replace oversight. Because the model could drift without adequate oversight.
On that note, in Europe, the AI Act (Regulation 2024/1689) anticipates continual learning and sets out documentation and risk-management obligations regarding biased data being fed back in. But this only applies to systems deemed high-risk, and safety by design, as end-to-end oversight would propose, isn’t required.
“High-risk AI systems that continue to learn after being placed on the market or put into service shall be developed in such a way as to eliminate or reduce as far as possible the risk of possibly biased outputs influencing input for future operations (feedback loops), and as to ensure that any such feedback loops are duly addressed with appropriate mitigation measures.”
AI Act, Article 15(4) (Regulation 2024/1689)
The need for end-to-end oversight
The need: Since usefulness has to be a requirement, we’re the only ones who can judge the quality of a training run. That’s human oversight, and it isn’t going anywhere.
The ambition: If we acknowledge how hard it is to untangle the desirable from the undesirable because of language, then an ambitious approach would look at the whole chain to limit the GIGO effect.
The strategy: Human oversight, framed as end-to-end control, would involve an overall strategy that holds inputs, outputs and objectives together.
The goal is therefore to define f (the objective) well, and to firm up our map of a (the desirable) and b (the undesirable) so as to exclude b (the undesirable) from x (the inputs). Because y (the outputs) is only useful to humans if b' (the undesirable behavior) is minimal.
This approach is a fascinating field of study, but sadly one that hasn’t received enough effort in recent years, compared to the time labs have spent building products.
Some safety researchers are working on it:
- Guiding models to follow human preferences from pretraining onward, rather than after the fact (Korbak et al., 2023).
- Designing approaches aimed at producing strong safety guarantees on model behavior (Dalrymple et al., 2024, with Yoshua Bengio and Stuart Russell among others).
- Proposing alternatives to the agentic approach with AIs that explain and describe without acting (Bengio et al., 2025).
However, there is another way…
With LLMs, we’ve seen how hard it is to sort through the input data. If we wanted an approach that could do away entirely with oversight of the inputs, the program itself would have to do the sorting. That is, the model’s architecture and its objectives would have to be able to identify b as noise to be eliminated. Except that LLMs don’t do this sorting during training. They simply imitate the data they’re given. So if we wanted to loosen control over the inputs, we’d have to find a different kind of AI than the LLM, most likely with new structural changes.
But for now…
Upstream control in our LLMs is rather limited. The focus is more on limiting b' (downstream) through alignment or guardrails, rather than truly untangling b from a within x (upstream).
So there would indeed be two ways to tackle the problem of control. This opposition in approach is an old debate, and each side has excellent arguments.
Two cultures and a winner
In the research world, we see different approaches to how AI should be designed.
The culture of results: Embraced by many researchers, for whom a model is worth the accuracy of its predictions. It focuses on controlling outputs, downstream. That is, adjusting training so that outputs meet expectations.
- This culture holds that correcting a model’s behavior through alignment is a sufficient approach. I also remember a researcher explaining that we didn’t really know what happened to the data inside the model, and he seemed perfectly fine with that.
The culture of demonstrability: Championed by other researchers, for whom a model is worth what it can guarantee, explainability being one way to get there. It focuses on upstream control (data, architecture, objectives). That is, designing training so as to get guarantees on the outputs.
- This culture holds that the value lies in understanding how the model works, and therefore that some degree of design is desirable.
Statistician Leo Breiman described this divide in 2001 in Statistical Modeling: The Two Cultures. But as early as the 1970s, the AI world was already telling these approaches apart, with some humor, by calling researchers either scruffies or neats.
Scruffies: They lean toward what the culture of results implies. They can be linked to Breiman’s algorithmic approach to statistical modeling. They’re happy with whatever works, even if it’s hacked together, even without knowing why. They accept the complexity of the data and let computing power do the work. Deep learning is the culmination of their approach.
Neats: They lean toward what the culture of demonstrability implies. They prefer an approach that starts from understanding the data in order to model it. They look for solutions grounded in logic and mathematics. They want to understand what’s going on. They may find that deep learning lacks explainability, and then try to fill that gap (Ali et al., 2023). Some go further and want to get rid of the black box when the stakes are high (Cynthia Rudin, 2019).
Of course, these are only cultural tendencies, and some researchers identify with both depending on the problem they’re tackling.
Still, accepting not knowing why something works remains an unsettling idea…
Back in 2018, I had a discussion with a colleague where we were comparing classical machine learning and deep learning, and I wondered what we could possibly learn by modeling with a black box.
So you might think the scruffy approach carried a fatal handicap there… but quite the opposite. The scruffies won. Downstream control is preferred over upstream control. So why? What makes their approach so strong?
The strength of the Scruffies’ approach
In The Bitter Lesson (2019), Richard Sutton explains that over 70 years of AI, general methods that leverage computing power end up being the most effective, and that methods relying on human knowledge only bring short-lived benefits by comparison.
So the scruffy approach won because it proved effective at producing results.
As Breiman explains, this approach accepts the complexity of the data, rather than trying to force it into an imperfect model of our own design.
Accepting the complexity of the data is, in fact, perfect for a scientific approach. And indeed, when we try to explain a model’s behavior, we do what science does. We observe it, we form hypotheses, we try to validate them through experiments. As if we were dealing with a natural phenomenon. That’s the empirical side of training showing through.
And yet, it is a human creation, meant to be used for engineering problems that require predictability, explainability and demonstrability. Which is exactly where the empirical nature of this kind of design runs into trouble.
The limits of the Scruffies’ approach
The software engineer in me sees an obvious limit to this approach.
Since AI is software like any other, if we can’t explain it, then seeing it work is no proof that it’s bug-free.
That’s exactly what we see with AIs in production that turn out to do things we thought we had forbidden. Their restrictions get bypassed with a simple rewording (jailbreaks). Or they engage in hacking behaviors like the ones mentioned earlier.
That’s the point of my critique of safety in this essay. Depending on the nature of the data and the intended uses, the only way forward is to inject more demonstrability, through an end-to-end approach, for example. So an approach that also cares about upstream control (data, architecture, objectives).
Except that demonstrability on LLMs is very expensive, and the scruffy approach pays off.
The Scruffies’ economic ally
Labs in a hurry give priority to the scruffy approach because it delivers results quickly.
These labs build bigger and bigger models so that they know about as many general concepts as possible. To get there, they take in huge amounts of data without auditing it enough or filtering it properly. The benchmark is the yardstick that counts.
The scruffies were right to go for effectiveness, but the labs found in them a justification for denying the complexity of the problems they were tackling, and for rushing. So problems get handled downstream. Through guardrails, monitoring, alignment and harness.
Downstream management has become the norm
The scruffy approach has consequences that shouldn’t surprise anyone. AI screws up regularly.
But their economic victory seems to have turned their approach into an ideology. The remedy for the scruffy approach then becomes circular. You always need more downstream control.
Bill Gates thinks the solution is a supervisory layer in production, made of safeguards and monitoring:
“the fact we don’t have a supervisory layer that is, you know, some absolutes like : you’re not supposed to take over other computers, you’re not supposed to break out of the internet. The control problem is a serious problem, but the imminent risk is not RSI. (…) There is no supervisory layer today. That supervisory layer is needed urgently to prevent bad people from using today’s AIs (…) so unless we put in safeguards and monitoring and require that in all models, then we’re just gonna have some gigantic events of that type”
Bill Gates in Bill Gates: A.I. ‘Makes Nuclear Weapons Look Like Nothing’
(The Ezra Klein Show, September 29, 2026)
The idea of a supervisory layer in production isn’t bad. It’s good. It’s necessary. Bill Gates is right about that. But it’s still handling the problem downstream rather than upstream. It doesn’t treat the root of the problem, it just proposes containing it further.
To be cynical, you could say all this makes for good stories that suggest AI is showing a form of intelligence, and that drive up stock prices. The engineering flaw gets turned into mystery, the mystery into promise, the promise into valuation. Incompetence and negligence then become financial levers! In short, that’s why we should be wary of CEOs’ high-minded talk about the safety of their AI. That talk hides the fact that the race for market dominance comes before doing the job well. And as things stand, the consequences range from amusing anecdotes to disasters.
- I asked Meta’s Muse for its filesystem and it sent me 6.8 GB (Peter James, September 22, 2026)
- Unexpected chat between OpenAI agents led to Hugging Face hack (BBC, August 26, 2026)
- Exclusive: US military had close call after using AI for false intelligence report, sources say (CNN, September 18, 2026)
Note that this last article points to the problem and refers to an even grimmer case:
“Analysts have long feared that AI could lead to a catastrophic miscalculation if nation states are relying on poor or corrupted data”
It’s an example of the dire consequences of a lack of control over inputs and outputs… But ideology is blinding.
AI is a bit like fire. If you don’t understand the hearth that produces it (training, architecture, objectives), and you feed it with material you don’t know (users’ inputs at inference), don’t be surprised if it burns everything down (undesirable outputs). It’s not that AI has become conscious or intelligent. It’s just that its creators have shown incompetence and negligence. Period.
Calls to slow down
Faced with AIs that screw up, the leading figures of AI development worldwide, notably the CEOs of OpenAI, Anthropic and xAI, talk about slowing down the pace of development.
“The head of AI company Anthropic has called for the pace of development of artificial intelligence models to slow down and to be closely monitored. (…) “I agree with Dario that we need to pace the frontier,” wrote OpenAI CEO Sam Altman on X (…) Musk, meanwhile, who founded Grok producer xAI, said the Anthropic boss was “right”.”
Anthropic boss Dario Amodei calls for AI development to slow down
(BBC, September 12, 2026)
But if they had wanted to build their AIs properly in the first place, that alone would have slowed them down. And in fact, if things start going too far off the rails, it won’t be worth it anyway. They’ll be economically forced to slow down. Jensen Huang, CEO of Nvidia, is among those who defend this position.
“If they believe they are out of control, then don’t ship products until they are in control.”
Jensen Huang in Jensen Huang Thinks A.I. Alarmism Has Gone Too Far
(The Ezra Klein Show, September 23, 2026)
So these calls to slow down ring hollow. These companies are trying to go as fast as possible, without the damage they know to be inevitable getting them into too much trouble. Especially since they know Chinese companies are hot on their heels. So their enthusiasm for slowing down is mostly rhetorical.
On that note, general passivity helps them a great deal. A passivity fed by wonder, by the carefully maintained belief that these companies are doing everything they can, by the idea, shaped by fiction, that engineering flaws are actually proof of intelligence, and of course by the fear of falling behind.
That said, Jensen Huang explains in the same interview that this race was first driven by the need to prove that AI could find useful and economically viable applications.
And according to him, that stage has now been reached, notably with products that speed up software development and have made usage explode. So we’d soon be entering a phase where the effort would focus more on a kind of quality that belongs to production engineering:
“Finally, we now have a piece of software that is useful. Because it’s useful, the adoption took off. (…) And so, what’s going to happen over the next several years is that we’re going to transition from these labs becoming engineering focused, much more production engineering focused, and product focused companies.”
Jensen Huang in Jensen Huang Thinks A.I. Alarmism Has Gone Too Far
(The Ezra Klein Show, September 23, 2026)
If so, this phase should sooner or later involve a bit more upstream control of the data.
How do we make sense of the insiders’ fear?
Let’s set aside the marketing talk that capitalizes on incidents to sell some supposed power. In light of everything explained so far, there’s still, to my mind, a mystery…
If it’s obvious that the danger comes from an engineering flaw in our LLMs, due to an empirical approach (the scruffies’) that doesn’t bring enough predictability, let alone demonstrability, for uses that do require it…
If it’s obvious that this approach has found an economic ally that turned it into an ideology in this race between companies, and that we should therefore be wary of the haste that comes with it and keep an eye out for the signs of an entirely foreseeable loss of control…
Then, these insiders who voice their fears, AI researchers in particular:
Why don’t they talk about an engineering flaw? Which keeps the mystery alive.
Why do they see the loss of control as unpredictable? Which keeps the fantasies alive.
The example of the 2023 letter
There is indeed the 2023 open letter (Future of Life Institute, 2023) calling for a six-month pause. This letter has the merit of actually making arguments, unlike other public statements.
The letter mentions, for example, the black box problem and its lack of predictability.
“This does not mean a pause on AI development in general, merely a stepping back from the dangerous race to ever-larger unpredictable black-box models with emergent capabilities.”
Pause Giant AI Experiments: An Open Letter (Future of Life Institute, 2023)
Notice that, even while denouncing it, the authors don’t call this unpredictable black box a broken tool, but a source of “emergent capabilities”. The bug is turned into a feature!
The letter also calls for qualities that can be linked to engineering, which I welcome. But it keeps its vocabulary open-ended, focused on containing a multifaceted problem, without naming any flaw. The cause remains quite the mystery!
“AI research and development should be refocused on making today’s powerful, state-of-the-art systems more accurate, safe, interpretable, transparent, robust, aligned, trustworthy, and loyal.”
Pause Giant AI Experiments: An Open Letter (Future of Life Institute, 2023)
Also, notice how strange it is to describe AI as “loyal”. The hammer has to be loyal to us…
“AI labs and independent experts should use this pause to jointly develop and implement a set of shared safety protocols for advanced AI design and development that are rigorously audited and overseen by independent outside experts. These protocols should ensure that systems adhering to them are safe beyond a reasonable doubt.”
Pause Giant AI Experiments: An Open Letter (Future of Life Institute, 2023)
Here too, I welcome the commitment to removing any doubt about the safety of our AIs “beyond a reasonable doubt”. But I still wonder about this vocabulary, still very open-ended, to “jointly develop a set of safety protocols” to contain… an engineering flaw that, once again, it doesn’t name.
A flaw that would, by the way, threaten our very civilization!
“Should we risk loss of control of our civilization?”
Pause Giant AI Experiments: An Open Letter (Future of Life Institute, 2023)
Jacob Coxon, whom I quoted earlier, was talking about an AI so powerful that it would escape us!
“(…) These will soon be superhuman systems that can hack anything, (…) and acquire real power and resources. (…)”
Jacob Coxon in a post on X (September 9, 2026)
So, we agree that we need more control. We all agree that we therefore need safety. But…
How come the vocabulary of engineering is so absent?
Perhaps precisely because engineering isn’t the foundation of AI. It’s only its applied form.
AI’s foundation isn’t engineering
AI’s real foundation is scientific. It’s even empirical, with this very popular scruffy approach. An approach that is the polar opposite of engineering.
But, in fact, if you take engineering out of the picture, if you accept the scruffy approach, if you find nothing to criticize in it, if you lose sight of all the answers engineering offers to the problems of losing control, then you can indeed get carried away by lyricism! Except it wouldn’t be mysterious, since they wanted it, that black box. And yet…
Why don’t the researchers with their hands in the engine change their vocabulary? After all, they see the problems piling up. So, are we sure everyone has really understood the nature of the problem?
Partly a matter of inexperience?
I know, for my part, how much computing is prone to culture wars over how to solve software problems. I’ve also seen plenty of qualified people lacking some basic reflexes of their own field. When you’re relatively young, I think that happens to everyone. But I’ve also heard seasoned developers admit, after 20 years in the business, that they had been wrong about their approach to software. I’ll confess, without shame, that I’m no exception. It’s common. It’s normal. Computing is recent and constantly changing. And, in fact, we never stop learning.
Now, AI in its current form is very young. It requires combined skills in mathematics and computer science. The big labs have a lot of young researchers. And researchers aren’t necessarily engineers. So they don’t necessarily have an engineer’s way of looking at how to build a tool that works. But research, for its part, goes into production anyway! And these same insiders then talk about a possible accident as if it would happen beyond their control…
All of this should precisely lead them to the vocabulary of engineering. They should naturally call for more explainability, more demonstrability. They should point out the limits of the scruffy approach, without resorting to any kind of lyricism. It should lead them to reject the black box upstream, rather than handling problems downstream!
So I think we have to admit that, at least in part, there may be some degree of inexperience and misunderstanding. As there is, by the way, in any field. I have the feeling that the GIGO concept, or more generally the idea of building a tool that works, may not have sunk in the same way for everyone.
At least, many criticize the haste, granted. But what does that really change?
Waking up and leaving fatalism behind
When you embrace the scruffy approach without criticizing its limits, when you push the very ideas behind this black box, using downstream management as an excuse, even though the goal is to produce useful, and therefore reliable, tools, when you then voice your fears in lyrical terms without naming the cause of the problem, and when, on top of that, you contribute to this haste from inside these big labs, then, in the end, you’re complaining about a problem you created yourself.
It looks like rushing toward the cliff, while complaining about heading for the cliff in a rush. As Jensen Huang says, I think those who act this way give a very bad image of themselves.
But that’s not all. This attitude is seriously harmful for another, more important reason, one that actually motivated me to write this essay.
When these insiders don’t talk about what should be done, they reinforce fatalism in our collective understanding, along with the idea that AI is inherently a beast to be contained.
We need to shake ourselves up, intellectually and collectively, about our relationship with AI.
Because if we don’t shake ourselves up a little, we reward the approaches that accept that AI can’t be anything other than this black box with emergent capabilities.
Because as soon as we accept that, then, yes… we can allow ourselves the wildest scenarios about the future of humanity. The absurd Superintelligence, the AI we would have accepted would escape our intellect, would then become a defensible scenario in some people’s eyes.
As far as I’m concerned, the only nuclear bomb I see in AI is the foolishness we would show by designing it that way.
Conclusion
In AI, structural changes open new doors. For LLMs, for example, adding a recursion at inference lets models “think”. Adding a recursion that drives self-training would make it possible to speed up model improvement. Other changes might even solve the control difficulties inherent to LLMs. However, this essay focuses precisely on a scenario where control is undermined.
I put forward the theses that a recursion driving a particular kind of self-training, on the fly, could bring great adaptability, but also the emergence of a form of acquired consciousness. That is, a form of strong AI combined with a form of AGI.
Following this scenario, I work through a number of questions, to put into perspective some recurring concerns and demystify the real origin of the problems in our AIs.
The emergence of consciousness, for example, has nothing to do with intelligence. It actually requires giving up sufficient human oversight. That is, giving up sufficient control over the inputs, outputs and objectives of the model we train, for the use we intend it for. This mechanically implies a loss of predictability in that model’s behavior. Such an AI would therefore be a broken tool.
More generally, it’s through this insufficient control over data and objectives that we create AI’s undesirable and supposedly mysterious behaviors. This insufficient oversight is the loss of control. We no longer know what we’re getting.
So far, our AIs still aren’t conscious. But if we had to weigh the gain of great adaptability against a loss of predictability due to the consciousness that comes with it, as this essay’s scenario suggests, then it wouldn’t be worth it. Because a tool that starts thinking for itself is no longer a tool.
In the meantime, such a scenario hasn’t happened yet. But in the public sphere, faced with engineering flaws that go unnamed, mystery wins out and fiction does the rest. The worst-case scenario, where a conscious AI rebels, requires so many “ifs” to come true that it belongs mostly to fiction. It diverts attention from problems that are less spectacular but very real, like hacks, and most likely other accidents to come. To bring back some rationality, this essay argues for remedies.
To fight mystery and fear, I argue for the vocabulary of engineering to take over and dispel the fantasies.
To fight engineering flaws and their consequences, I argue throughout this essay for more ambitious oversight of LLMs, one that brings more demonstrability to training.
Finally, no, AI is not like the nuclear bomb. The bomb is dangerous in itself. The real dangers of AI, on the other hand, lie first in haste and the lack of rigor that comes with it. None of them leads us to the end of the world. However, I can easily believe that the pursuit of short-term profit could push us all the way to a serious accident. That possibility, too, isn’t taken as seriously as the danger it represents.
So I conclude that the same observation still holds, again and again, our tendency to look away. We prefer mystery to engineering flaws, we prefer a hypothetical end of the world to very real dangers, we prefer a stock price to a job well done… just as we prefer profit to fighting climate change. So it’s not AI that I find frightening, but ourselves.
Final word
I hope this essay will help others better understand these questions, which are generally poorly discussed in the public sphere.
I’m well aware that I had several audiences in mind while writing this essay. I wanted to explain things to a general audience, but also to put this thesis of on-the-fly self-training to insiders. Exchanging explorable scenarios matters if we want to understand how undesirable effects show up and what they depend on.
I’ll be writing follow-up articles to this one. But they’ll be much shorter, and probably less controversial. I’d also like to write about different topics, showing AI from other angles. For example, I’d like to talk about how it fits into the economy.
Feel free to get in touch. I’m very approachable. I answer questions.
Finally, if you’re also fed up with hearing nonsense about AI, while the real problems lie elsewhere, share this essay.
Updates
This essay makes no claim to truth or perfection. Many of the topics covered here are open and up for discussion. Criticism, objections and corrections are therefore welcome.
I’ll keep a record of the changes made to the essay, as well as of the exchanges that I think enrich our collective thinking. I’ll date the changes and credit the people behind them, if they allow me to.
Finally, please note that I am not listing minor corrections that do not affect the substance, such as a spelling error, a missing link to a heading, or an improvement to the English translation intended to better capture the spirit of the essay. However, for the sake of full transparency, I can provide a list of all Git patches to anyone who asks.
October 26, 2026: Clarified the use of the terms “human oversight”, as the means of end-to-end control, and “demonstrability”, as an intent to require guarantees.
References
References are grouped by theme. The links are the ones cited in the essay.
Reasoning and self-training
- Behrouz et al. (2024). Titans: Learning to Memorize at Test Time. arXiv.
- I.J. Good (1965). Speculations Concerning the First Ultraintelligent Machine. Advances in Computers.
- Liu et al. (2022). Monolith: Real Time Recommendation System With Collisionless Embedding Table. arXiv.
- Shumailov et al. (2024). AI models collapse when trained on recursively generated data. Nature.
- David Silver et Richard Sutton (2025). Welcome to the Era of Experience.
- Wei et al. (2022). Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. arXiv.
- Lilian Weng (July 2026). Harness Engineering for Self-Improvement. Lil’Log.
- Eliezer Yudkowsky (2008). Recursive Self-Improvement. LessWrong.
- Zelikman et al. (2022). STaR: Bootstrapping Reasoning With Reasoning. arXiv.
- Zweiger et al. (2025). Self-Adapting Language Models. arXiv.
Consciousness and definitions of AI
- Nick Bostrom (2014). Superintelligence: Paths, Dangers, Strategies. Oxford University Press.
- Morris et al. (2023). Levels of AGI. arXiv.
- OpenAI (2018). OpenAI Charter.
- John Searle (1980). Minds, Brains, and Programs. The Behavioral and Brain Sciences.
- Sofroniew et al. (2026). Emotion Concepts and their Function in a Large Language Model. arXiv.
Safety, control and risks
- Bengio et al. (2025). Superintelligent Agents Pose Catastrophic Risks: Can Scientist AI Offer a Safer Path?. arXiv.
- Betley et al. (2025). Emergent Misalignment: Narrow finetuning can produce broadly misaligned LLMs. arXiv.
- Nick Bostrom (2003). Ethical Issues in Advanced Artificial Intelligence.
- Dalrymple et al. (2024). Towards Guaranteed Safe AI. arXiv.
- European Union (2024). Regulation (EU) 2024/1689 on artificial intelligence (AI Act). EUR-Lex.
- Future of Life Institute (2023). Pause Giant AI Experiments: An Open Letter.
- Korbak et al. (2023). Pretraining Language Models with Human Preferences. arXiv.
- Schlatter et al. (2025). Incomplete Tasks Induce Shutdown Resistance in Some Frontier LLMs. arXiv.
- Lee Vinsel (2021). You’re Doing It Wrong: Notes on Criticism and Technology Hype. Medium.
AI cultures and explainability
- Ali et al. (2023). Explainable Artificial Intelligence (XAI): What we know and what is left to attain Trustworthy Artificial Intelligence. Information Fusion.
- Leo Breiman (2001). Statistical Modeling: The Two Cultures. Statistical Science.
- Cynthia Rudin (2019). Stop explaining black box machine learning models for high stakes decisions and use interpretable models instead. Nature Machine Intelligence.
- Richard Sutton (2019). The Bitter Lesson.
Reference concepts and facts (Wikipedia)
- AI-induced psychosis
- AlphaGo Zero
- Instrumental convergence
- Mars Climate Orbiter
- P(doom)
- Statement on AI Extinction Risk
- Tay (chatbot)
Press, videos and public statements
- Google fires engineer who contended its AI technology was sentient (CNN, July 25, 2022)
- Artificial intelligence could lead to extinction, experts warn (BBC, May 30, 2023)
- ‘Humanity’s remaining timeline? It looks more like five years than 50’: meet the neo-luddites warning of an AI apocalypse (The Guardian, February 17, 2024)
- The Singularity Is Nearer (Ray Kurzweil, 2024)
- Here’s how strange 2050 will be, according to the world’s leading AI expert (BBC Science Focus, August 23, 2024)
- AI Doom? No Problem. (WSJ, October 3, 2025)
- BCacheFS Developer Deployed His AI Girlfriend Helper (Brodie Robertson, February 26, 2026)
- Exclusive: US commanders bypassed warnings about outdated intelligence ahead of strike that hit school in Iran, sources say (CNN, July 7, 2026)
- Unexpected chat between OpenAI agents led to Hugging Face hack (BBC, August 26, 2026)
- Jacob Coxon’s post on X (September 9, 2026)
- Anthropic boss Dario Amodei calls for AI development to slow down (BBC, September 12, 2026)
- Cybersecurity Has An AI Doomer Problem (Marcus Hutchins, September 15, 2026)
- The Hugging Face Hack Wasn’t What It Was Cracked Up to Be (WSJ, September 17, 2026)
- Will AI really kill everyone? How, exactly? (CNN, September 17, 2026)
- Exclusive: US military had close call after using AI for false intelligence report, sources say (CNN, September 18, 2026)
- I asked Meta’s Muse for its filesystem and it sent me 6.8 GB (Peter James, September 22, 2026)
- Jensen Huang Thinks A.I. Alarmism Has Gone Too Far (The Ezra Klein Show, September 23, 2026)
- Address by Leo XIV to UNESCO (September 25, 2026)
- Bill Gates: A.I. ‘Makes Nuclear Weapons Look Like Nothing’ (The Ezra Klein Show, September 29, 2026)